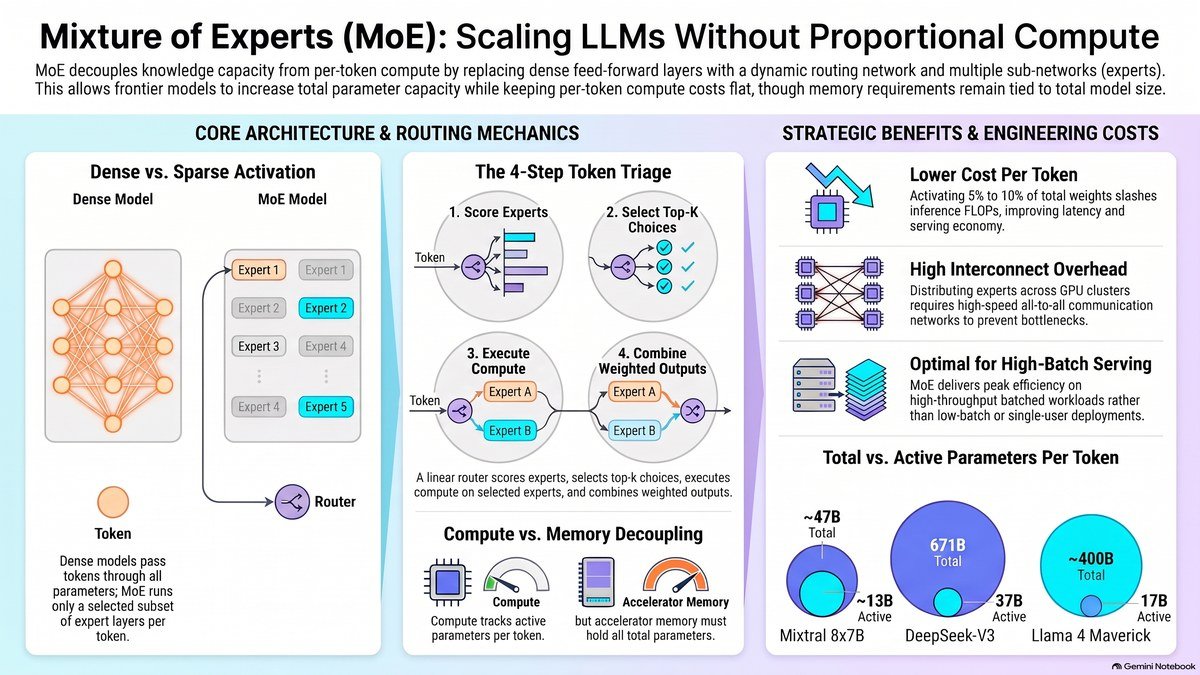
How Mixture of Experts works: gating networks, top-k routing, sparse activation, load balancing, and why frontier LLMs use MoE to scale capacity without scaling inference cost proportionally.
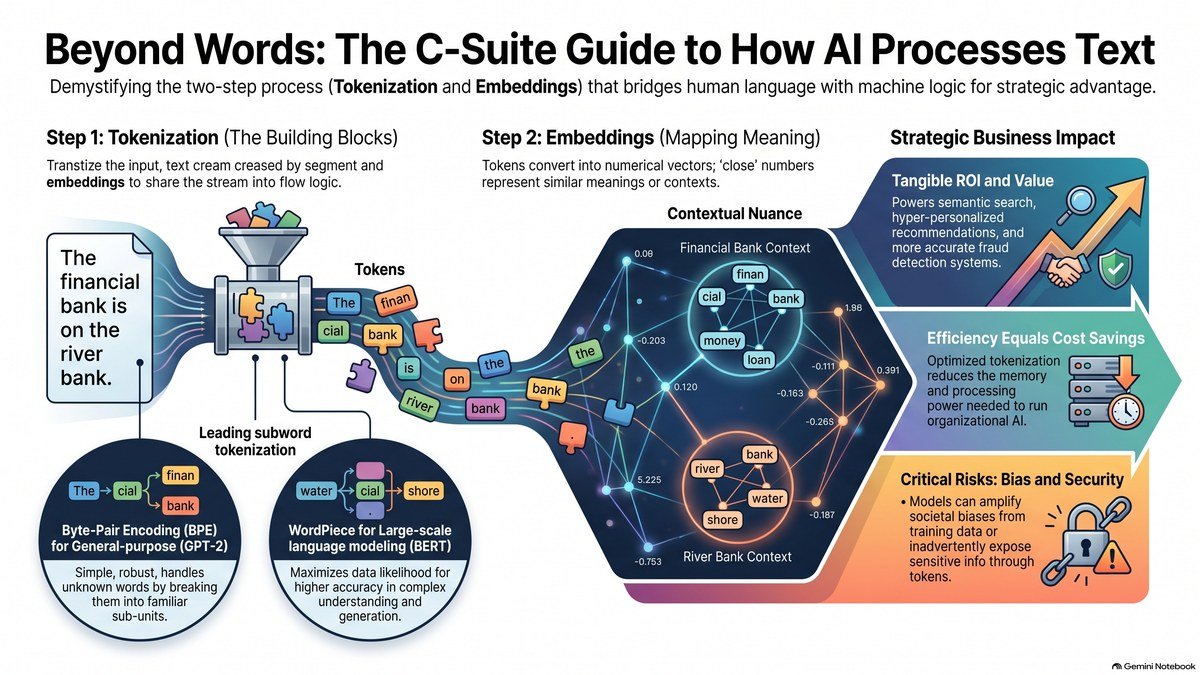
Unlock the strategic value of AI by understanding how models process text. This deep dive for C-suite explains tokenization (BPE, WordPiece), embeddings, business value, risks, and adoption choices.
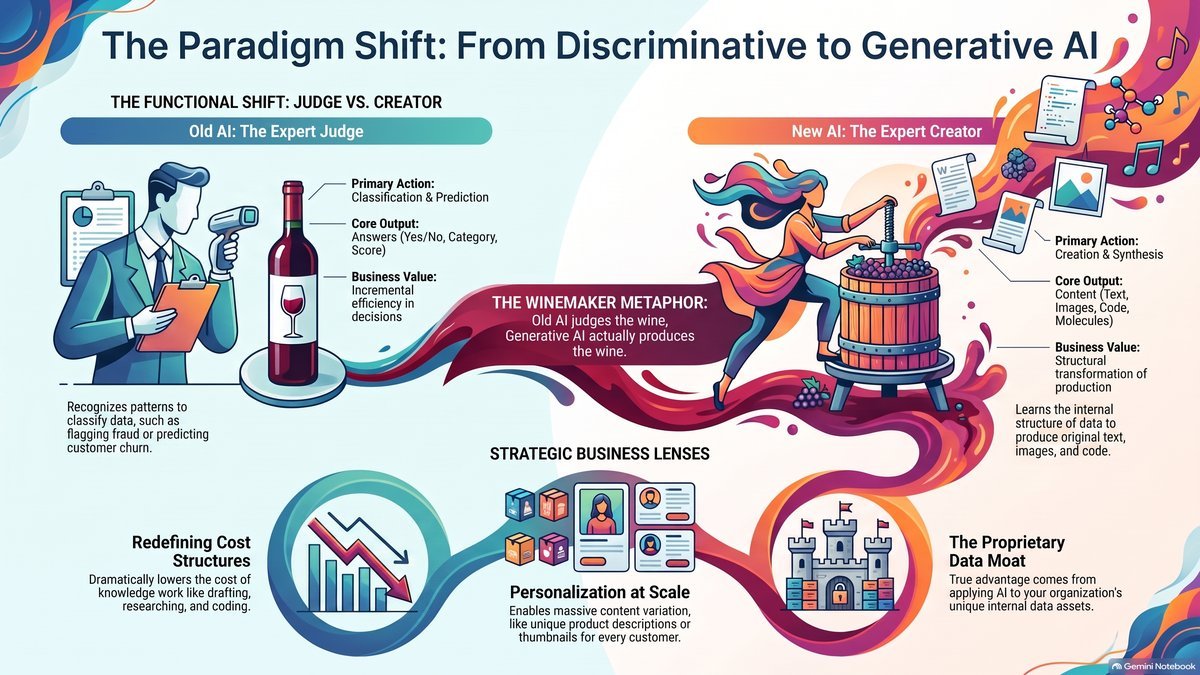
Understand the fundamental shift from discriminative to generative AI — how probability distributions, data generation, and five core architectures are reshaping machine learning.